Linum v2 was bottlenecked by the enormous size of its attention context window. A 720p, 5 second clip cost a whopping 110K tokens. To put that in perspective, LLMs see samples with fewer than 8K tokens for 97% of their pretraining. Attention is quadratic in cost, so the biggest lever we have to accelerate model training is pruning the context window down.
Most generative image and video systems are Latent Diffusion Models (LDMs). They split compression and generation into independently trained modules: the Variational Autoencoder (VAE) and the DiT (Diffusion Transformer). Recently, pixel-space models like the JiT have shown to be a promising alternative. It reduces two models into one and allows the diffusion model to construct a latent space specifically for generation, rather than rely on one built for reconstruction.
When trained on our (image, caption) dataset, the JiT seems to struggle to produce finegrained details. We propose a novel encoder-decoder architecture (JiT-DDT) that recovers this detail and trains much more efficiently than its LDM counterpart. Against our Linum v2 baseline, the JiT-DDT trains a text-to-image model with 3.6× fewer GPU-hours, even though it generates images with 4× the pixels.
3.6× faster to train, at 4× the pixels
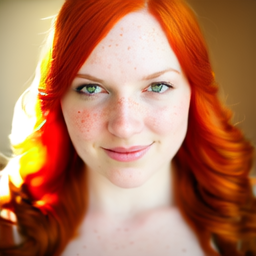
Linum v2 (ours, previous)* · 256×256
2.0B latent-space DiT + VAE
256 latent tokens
* image-only checkpoint
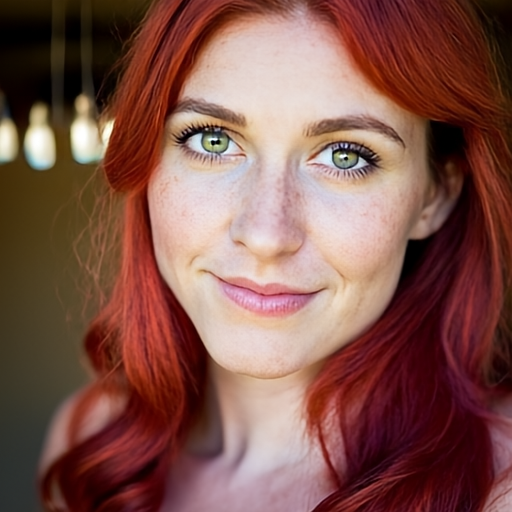
JiT-DDT (ours, new) · 512×512
2.5B active pixel-space DiT
320 pixel tokens = 64 encoder + 256 decoder
GPU-hours
samples seen
Research release


JiT-DDT code and model weights are available under the Apache 2.0 license. We hope that by sharing our findings with the broader community, we can encourage others to also explore more efficient training methods. This should be treated as a research artifact, not a full model release. Stay tuned for more research checkpoints like this, en route to Linum v3.
Hitting the VAE compression wall
Almost all generative image and video models are Latent Diffusion Models (LDMs). These have two key components, a Variational Auto Encoder (VAE) for compression and a Diffusion Transformer (DiT) for generation.
Operating in raw pixels is too expensive (especially for video), so we first need to find a way to reduce RGB pixels into a smaller amount of tokens for the DiT. This is where the VAE comes in. It's trained for compression and reconstruction. Specifically, it pushes our pixel-space samples through a probabilistic encoder, spits out -dimensional tokens, and then pushes these latent tokens through a probabilistic decoder to land back in pixel-space.
The VAE is trained to compress and reconstruct
When building a LDM, you train the VAE separately and then freeze it (i.e. no gradient flow from the DiT into the VAE). This way the latent space stays static throughout the course of DiT training. You run the VAE's encoder to embed your data, train the DiT to traverse the VAE's latent space, and then transform the DiT-generated latent tokens into pixel space using the VAE's decoder.
The VAE is trained once and frozen;
the DiT learns to move through its latent space
We want to eke out as much token compression as possible from the VAE, so that we can curb the cost of attention in our DiT. But if you take a survey of the popular open source text-to-image models like FLUX, Ideogram, and Z-Image, you'll notice that they all cap out at 16×16 token reduction. This aligns with our experiments on Image-Video VAEs from a few years ago. Unfortunately, it seems like there is an empirical ceiling on the amount of compression we can get out of a standard CNN VAE without degrading the reconstructions.
Unlocking aggressive compression with a unified model
Last fall, Tianhong Li and Kaiming He published a paper (JiT) that achieves 32×32 token reduction by throwing away the VAE altogether and pushing the compression task into the DiT itself.
Patchify: 4×4-pixel patches → 48-dim tokens → linear bottleneck to 12
16×16 pixels, 3 channels (RGB) each
This approach to reducing token counts isn't particularly new. It was invented for vision transformers (ViT) half a decade ago, and it's pretty commonly paired with a VAE to further condense token sequences before they enter the DiT. We used it in Linum v2 and so do models like FLUX.
So, why hasn't anyone tried this before? This feels like a free lunch. You get a (potentially) lossless way to cut down attention cost, and it's bone-dead simple.
In early 2025, papers like VA-VAE demonstrated that DiTs struggle to learn from high dimensional inputs. Aggressive patchification explicitly pushes information into the channel dimension, so it triggers this instability. But as it turns out, this is not intrinsic to the architecture. Rather, it's downstream of the v-prediction, v-loss flow matching objective that everyone's been using to train diffusion models these past few years.
A quick refresher on flow matching
In old school 2022-era denoising diffusion (DDPM), we iteratively noise a sample and train a neural network to remove the noise. This way at inference time we can use our neural network to transform Gaussian noise into a sample from our data distribution over a sequence of steps. This formulation has a host of issues (e.g. oversaturation in generation, unstable learning, distillation collapse), so in the intervening years the field has shifted away from it towards flow matching.
In flow matching, we construct a straight line path between every sample in our data distribution and a sample of Gaussian noise:
At , we recover . At , we get , where . Then we train a network to approximate the velocity along that path:
We call this v-prediction, v-loss because the neural network is explicitly predicting velocity and it's trained on the MSE between its velocity prediction and the ground-truth, conditional velocity field.
V-prediction and the curse of dimensionality
If you're training a flow matching model you don't necessarily need to train your neural network to predict and regress velocity. The three terms are linearly re-arrangeable; so you can mix and match , , and across prediction and regression targets:
Nine ways to write one objective
Three targets, each linear in the other two
Rearrange one identity to fill each off-diagonal cell
In JiT, Li and He revisited the v-prediction, v-loss decision that the field's been making since the inception of flow matching. They took a toy distribution (points on a spiral) and then projected these points from 2D to different high dimensional spaces of increasing size. For each of these spaces, they trained flow matching models with x-prediction, -prediction, and velocity-prediction; and found that the x-prediction was the only model type to accurately generate samples from the spiral distribution at large dimensions. DiTs have been struggling to learn from high-dimensional inputs because of the curse of dimensionality.
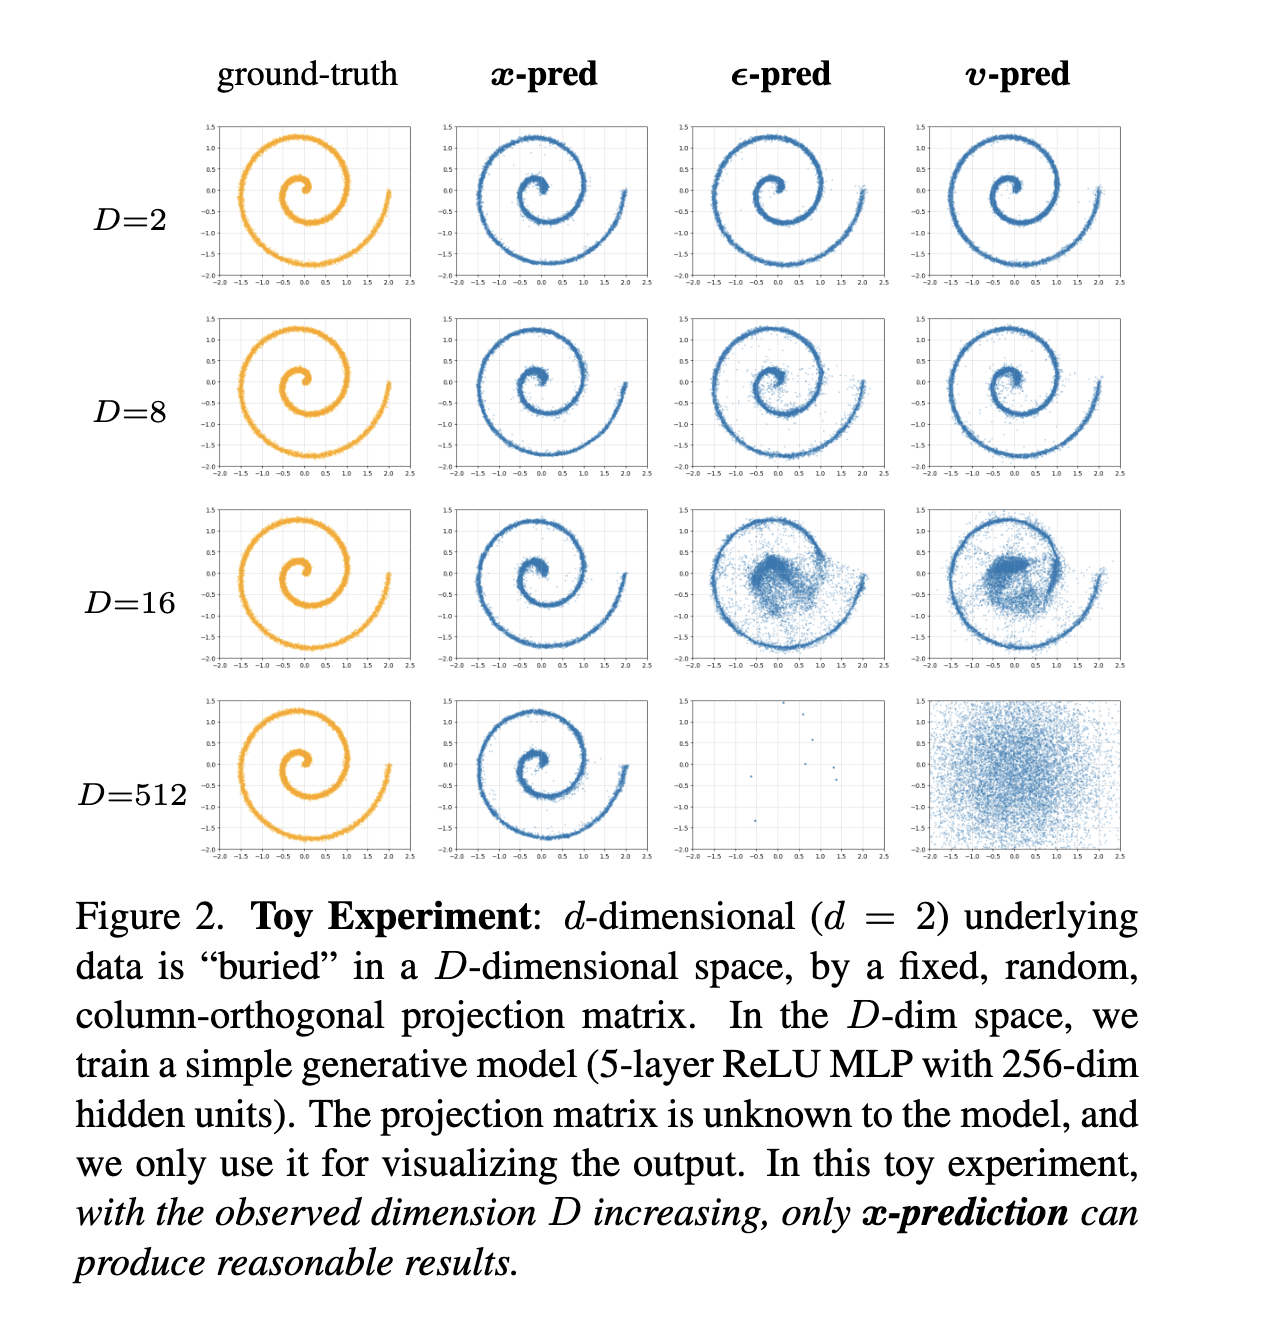
Velocity is . When we do v-prediction, our neural network has to implicitly learn the signal () and noise (). Noise is a random Gaussian that will cover the entire -dimensional space. So, as we scale the problem of fitting noise (within the velocity term) becomes exponentially harder. This is why aggressive patchification failed in the past and why LDMs have been struggling to learn from high-dimensional VAE latents. As we grow the channel dimension, we end up in the degenerate case where our DiT is struggling to learn high dimensional Gaussian noise.
By switching to x-prediction, we can try to side-step the curse of dimensionality. If we believe that images and videos naturally lie on a low dimensional manifold, we should be able to have our models predict effectively even with high .
Noise fills the whole D-dimensional ball; images sit on a thin sliver of it
ε ~ N(0, ID)
n = 0 · intrinsic dim = 512
x₀ ~ image manifold
n = 0 · intrinsic dim = 3
In high-dimensional space (D = 512), noise is truly random. It spreads across the entire space, is incompressible, and cannot be described by any smaller number of dimensions (left). Images are intrinsically low-dimensional, so even in a high-dimensional space they cluster in a small subspace (right).
By predicting v, the model has to learn both the noise ε and the structure. Noise is the harder of the two, and the bigger D gets, the more of the model's capacity goes to fitting it. By switching to x-prediction, the model can spend its full capacity on the low-dimensional signal, even when D becomes large.
Empirically this works, if you do x-prediction, v-loss. In turn, this unlocks our ability to apply aggressive patchification, blow up the channel dimension, and push the compression problem into the DiT.
Extending JiT for text-to-image models
When we read about JiT, we were really excited to give it a go, since it was explicitly able to achieve 32×32 token reduction. But, we'd be remiss to say this is the only way to achieve this level of compression. Or, that everyone agrees that this is the best way to achieve this amount of compression.
LTX has been able to do this in their video models by altering their VAE's decoder to make it an explicit denoiser (i.e. they finetune the VAE decoder with a flow matching objective). More recently, Minimax H3 has achieved 32×32 compression in their VAE by swapping out the standard ~80-150M parameter CNN Decoder with a 2B parameter transformer (roughly the size of our entire Linum v2 model). And on toy benchmarks like ImageNet, LDMs still out-perform pixel space models by a smidge. Nevertheless, we think we can overcome some of the limitations present in the original JiT paper and match LDMs' performance in generative image and video.
Ideologically, we believe simple tends to beat complex when it comes to training neural networks at scale. Papers like E2E-VAE from last fall have shown that allowing your DiT to backpropagate (smartly) into the VAE can improve generation results and accelerate convergence dramatically.
To us, it makes logical sense that if we can specifically tailor the "latent space" for generation rather than rely on one built for compression, we can get better results. And we get the added benefit of having one cohesive model, rather than two disjoint ones.
We also think that ImageNet benchmarks on JiT understate its potential. The JiT might be able to achieve better compression than an equivalent VAE, by leaning on the scaffolding provided by the text prompts.
Text-to-image baselines
When we pretrained Linum v2, we relied on a VAE + patchification stack that afforded 16×16 token reduction. So, we trained on ~600M samples at 256px resolution before introducing 180p video and scaling up to 512px resolution.
For our JiT baseline, we wanted to get a sense of the output quality with the same image-latent-token budget. That meant we trained on 512px images with 32×32 token reduction.
JiT baseline
Linum v2 (ours, previous)* · 256×256
2.0B latent-space DiT + VAE
256 latent tokens
* image-only checkpoint
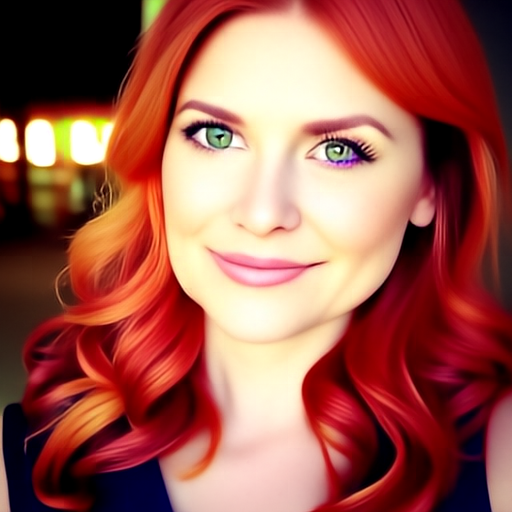
JiT (wide) · 512×512
2.0B active pixel-space DiT
256 pixel tokens
GPU-hours
samples seen
Our JiT setup
By moving from LDM to pixel-space, we transitioned from v-prediction, v-loss to x-prediction, v-loss. But, we also made a slew of other tweaks to the network:
One single-stream DiT does the compressing and the generating
- Single stream backbone
Instead of alternating blocks of self-attention (image/video) and cross-attention (text-to-image/video), we concatenate visual tokens and text tokens into a single stream that goes through the DiT. This increases the attention sequence in every block and increases the FLOPs per token, but should allow for significantly more expressive relationships between text and image tokens.
v2 block: self-attention, then cross-attention
v3 block: one self-attention over image and text - Wider instead of deeper
Our old model was a 40-layer transformer with 2048 hidden size. Here, we switch to a 23-layer transformer with a wider 2944 hidden size. Wider networks have become standard in recent DiT architectures (e.g. Z-Image), so we adopted the same.
- Perceptual losses
When you train a VAE, you use perceptual losses like LPIPS and adversarial loss via a GAN to push the reconstructions towards what humans like. MSE on its own gives you a blurry mess. Now that we don't have a VAE decoder, we need the JiT itself to leverage these losses to generate stuff humans like. We still use LPIPS, but instead of a GAN we use a P-DINO loss. Both are only applied when .
perceptual losses · both towers frozen · on x̂₀ vs x₀
- SiLU to SwiGLU
We swap standard SiLU non-linear activations with gated SiLUs (i.e. SwiGLU).
SwiGLU FFN · 2,944 → 7,936 → 2,944 · elementwise multiply
- Muon optimizer
Moonshot's Kimi models proved that the Muon optimizer works really well at scale. As they recommend, all the 2D matrices in our network (e.g. q/k/v matrices for attention, FFN weights) are optimized with Muon, while layers at the input/output of the network (e.g. patchification, output head) and scales/biases (e.g. AdaLN) are still optimized by AdamW.
- PixelREPA auxiliary loss
It's become pretty common to accelerate the convergence of your DiT by having an earlier layer in the network (e.g. layer 8 of a 23-layer transformer) align to the embedding of in an auxiliary model (e.g. DINOv3). This technique is referred to as REPresentation Alignment (REPA). We'll dig into this (and the limitations) later in the blog, so hold on for that. But for now, plain REPA did not work well for the JiT. Instead, we adopted PixelREPA which masks out x% of tokens in our visual token hidden state, pushes it through a shallow transformer, and then applies the typical cosine-distance loss between all visual tokens (including the masked tokens) and the auxiliary representation from DINOv3.
DINOv3 uses 16×16 patches. We need the token count between the DINO representation and our hidden state to match, so we downsample the images before they go through DINO. For example, if we're doing a 32×32 patchification on 512×512 images, we will have 256 tokens. We downsample the image to 256×256 before passing it through DINO's 16×16 patchification to also get 256 tokens.
PixelREPA · tapped after block 8 · x₀ downsized to 256px so DINOv3 gives 256 tokens
- Sigmoid attention gating
Now that we're moving from a cross-attention to a single-stream DiT architecture, we may be at a higher risk of attention sinks. We adopt sigmoid attention gating to neutralize this issue.
attention gate · 23 gates per block (1 for each attention head) · elementwise multiply
- Qwen text embeddings
Instead of T5-XXL text embeddings, we use hidden states from a more modern decoder-only LLM, Qwen3.5-4B. One downside to using a LLM is that it's unclear what hidden state to take as your embedding. Most modern LLMs use some sort of alternating sequence of sparse/linear attention and full-attention. We take the hidden states calculated after full-attention blocks, concatenate them together, and have the DiT learn a transform to combine these representations into a single text condition. Recent Ideogram and FLUX models are more aggressive here, using larger LLMs and aggregating information across all hidden states. Given the size of our DiT, it seemed like overkill to go down that path.
text conditioning · three hidden states, one learned projection
The JiT recipe
Noise schedule
At train time, we get to pick the distribution from which t is sampled. Empirically, there's a small band of values at high t where the structure of the image is determined. This is the hardest part of the trajectory for the model to learn, so we skew timesteps accordingly.
Note that the σ term is tied to pixel count: σ = 1 is for 256×256, σ = 2 is for 512×512. The intuition is that we need to shift more aggressively at higher pixel counts. There is more redundant information within the image, so we need to noise more. This is the exact schedule from JiT.
Loss
The MSE is x-prediction with the velocity weighting (x-prediction, v-loss), clamped at t = 0.1 so the weight caps out at 100×. LPIPS and P-DINO are perceptual losses on the predicted image. PixelREPA aligns the block-8 hidden state with DINOv3 features of the clean image (downsampled 2× to match the token grid of h₈).
Recovering finegrained details in pixel-space
One of the biggest limitations that folks have observed about JiTs is that they struggle to generate the finegrained details. Our baselines corroborate this. If we want to really get our pixel space models to sing, we need to fix this.
DDT: Decoupled Diffusion Transformer
LDMs face the same issue, but to a much lesser extent.
In early 2025, Shuai Wang and team tackled this problem directly with their DDT (Decoupled Diffusion Transformer), scoring SOTA on ImageNet gFID at the time. They observed that —
In each denoising step, diffusion transformers encode the noisy inputs to extract the lower-frequency semantic component and then decode the higher frequency with identical modules. This scheme creates an inherent optimization dilemma: encoding low-frequency semantics necessitates reducing high-frequency components, creating tension between semantic encoding and high-frequency decoding.
DDT abstract
DDT splits the model into two components, a "conditional encoder" for low-frequency structure and a "velocity decoder" for high-frequency detail. They give the encoder most of the layers, since the most difficult portion of the probability path to master is the transition from random noise to basic structure.
DDT splits one DiT into a large structure encoder and a shallow detail decoder
Within the encoder they apply REPresentation Alignment (REPA), an auxiliary loss that accelerates training by aligning the hidden states of an early layer of the model to the DINO representation of the clean image (). If you keep REPA loss active throughout all of training in standard DiTs, it actually hurts overall FID.
The DDT avoids this problem by giving the decoder the noised image () so it can extract the finegrained details that REPA might otherwise destroy. Moreover, the DDT frees up the decoder to focus solely on details by creating an information bottleneck. The decoder doesn't get the class label. Given its limited capacity, it's forced to rely on the encoder's hidden states to ascertain structure. And in turn, it allocates its parameters to focus on detail recovery.
JiT-DDT: our encoder-decoder pixel-space architecture
Naturally, we tried to port over the core ideas from the DDT so that we could recover detail in our pixel space model. We call this new architecture JiT-DDT (creative, we know).
Ours is trained with x-prediction, v-loss, unlike the DDT which was trained with the classic v-prediction, v-loss formulation.
This is crucial. If you downsample an image, you strip it of most of its high frequency detail, leaving behind low-frequency structure. So in an x-prediction-world, we can get our encoder to learn structure explicitly by predicting a low-resolution version of our input image, .
Concretely, we split our DiT in half. We give the encoder and decoder their own input patchification and output heads, so they can specialize. We have the encoder predict a 64×64 version of the input 512×512 image (8× downsampled) and pass its hidden states to the decoder. This way the decoder gets a structural sketch of the output, its own view of the noised image, and the text prompt to create the full resolution image.
JiT-DDT: the encoder plans a 64×64 image;
the decoder uses that plan, full-resolution x_t and text to generate the 512×512 image
One added benefit of this design is that we can have asymmetric patch sizes between the encoder and the decoder. If we're training on 512×512 images, the encoder will be tasked with regressing the 64×64 version of the image. It needs less information to do this task, so we can use 64×64 patches and operate on a 64-token sequence. Meanwhile, the decoder can use smaller patches to help recover detail (e.g. 32×32 patches or even 16×16 patches).
We make two additional deviations from the original DDT's architecture:
- Our encoder and decoder are equally sized. In the original DDT, the encoder predicted at the same resolution as the decoder. That's not the case for us. We've simplified the problem dramatically for the encoder by having it predict an 8× downsampled image, so it doesn't make sense to have the encoder be way bigger than the decoder. In the future, we'll have to run ablations to find the ideal encoder/decoder block ratio.
- Decoder gets the text condition. DDT was a class-conditional model on ImageNet. That's a relatively tiny domain compared to open world image and video generation. A lot of the detail that we want to recover will be annotated in the text, so we thought it'd be better to give the decoder access to this information. We tried removing the text condition in one of our ablations, and it was a wash. So, for the rest of our DDT experiments, we retain the text condition in the decoder.
The JiT-DDT loss: the encoder is scored on the 64×64 plan,
the decoder on the 512×512 image
Encoder · the 64×64 plan
Decoder · the 512×512 image
We compute the MSE loss twice, once for the encoder against an 8× downsampled version of x₀ and once for the decoder against the original x₀. We keep the alignment loss in the encoder, moving it earlier in the network (tapped after block 6 of 12, against DINOv3 features of x₀ downsampled 4× to match the token grid of the encoder's h₆). And, we keep the perceptual losses on the full resolution outputs of the decoder. The gradient runs end to end, so the decoder's loss trains the encoder too.
JiT-DDT 64/32 (baseline) reduces the oversaturation issue
JiT (wide) · 512×512
2.0B active pixel-space DiT
256 pixel tokens
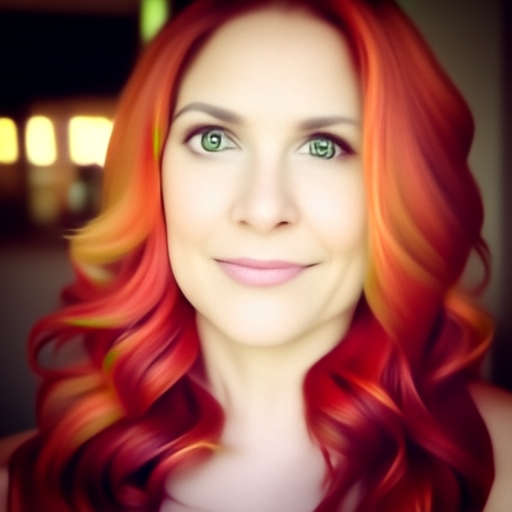
JiT-DDT 64/32 (baseline) · 512×512
2.2B active pixel-space DiT
320 pixel tokens = 64 encoder + 256 decoder
Adjusting the noise schedule
We were honestly surprised that the images from the JiT-DDT weren't that much better than the JiT. So, we ablated a bunch of different training and architecture decisions (e.g. warm-start the encoder before adding the decoder, dropping text from the decoder, etc.).
Nothing worked, until we started tweaking the noise schedule. It's the most obvious knob to tune, but somehow we haven't found any research dialing this in for pixel-space models.
Partway through training, widen the noise schedule toward clean images
training progress
phase 1 · LogitNormal(0.8, 0.8)
share of training timesteps within 0.08 to 0.13 · hover the plot to move
phase 1 · LogitNormal(0.8, 0.8)
<0.05%
phase 2 · LogitNormal(−0.2, 1.0)
3.0%
phase 2 / phase 1
107×
Widening the noise schedule helps JiT-DDT recover details like freckles and hair texture
JiT-DDT 64/32 (baseline) · 512×512
2.2B active pixel-space DiT
320 pixel tokens = 64 encoder + 256 decoder
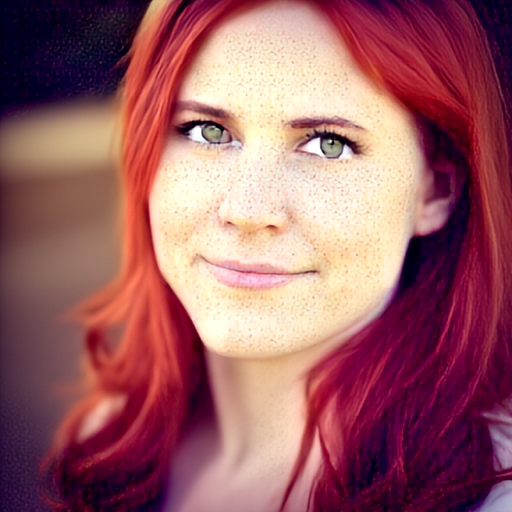
JiT-DDT 64/32 + noise shifting · 512×512
2.2B active pixel-space DiT
320 pixel tokens = 64 encoder + 256 decoder
Architecture refinements
Last fall, Alibaba's Z-Image became the best small, open-weight model on the market. Their technical report contains a lot of juicy details, but we were most interested in the tweaks they made to the architecture:
Four Z-Image changes to the DiT block
Refiners clearly helped our model. They're cheaper versions of the MM-DiT blocks invented by BFL in FLUX. Both help the model massage the modalities before combining them in a shared DiT trunk. The other knobs (AdaLN truncation, post-norm gate + tanh, RMSNorm) didn't move the needle for us, so we omit them from our experiments.
Refiners fix the excessive freckling and the color grading
JiT-DDT 64/32 + noise shifting · 512×512
2.2B active pixel-space DiT
320 pixel tokens = 64 encoder + 256 decoder
JiT-DDT 64/32 + noise shifting + refiners · 512×512
2.5B active pixel-space DiT
320 pixel tokens = 64 encoder + 256 decoder
The encoder and the decoder each get four modality-specific blocks before the shared DiT trunk: two for image, two for text (8 new blocks in total, 477M additional parameters).
We trimmed one shared block from each stack (2 total) which brought the refiner model within ~5% of the no-refiner model's FLOPs. The modality-specific blocks are much cheaper to run, since they see about half the sequence length of the shared blocks.
Note that the two runs shift the schedule at different points: the refiner model switches at 80M samples and trains 58M more under the wider schedule, while the previous model switches at 109M and trains 33M more.
From Linum v2 to JiT-DDT
We've covered a lot of ground, so let's recap real quick.
Our goal is to reduce tokens in the DiT context window. That way we can accelerate training and inference. Traditionally, DiTs have struggled to learn from high-dimensional inputs because of the curse of dimensionality implicit to v-prediction.
If we swap in x-prediction, we can get DiTs to successfully learn from high dimensional samples. We can use this fact to apply linear patchification, throw away the VAE, and push the compression problem into the DiT. This way we can develop the latent space specifically for generation and at the same time get the token savings we're looking for.
The one downside to this approach is that the JiT struggles to learn finegrained details out of the box. Humans perceive these details quite easily, so we need these if we want to generate good images and videos. Our JiT-DDT is one way we can get pixel-space models to learn structure and detail.
JiT-DDT trains in 3.6× fewer GPU-hours at 4× pixels
Linum v2 (ours, previous)* · 256×256
2.0B latent-space DiT + VAE
256 latent tokens
* image-only checkpoint
JiT (wide) · 512×512
2.0B active pixel-space DiT
256 pixel tokens
JiT-DDT (ours, new) · 512×512
2.5B active pixel-space DiT
320 pixel tokens = 64 encoder + 256 decoder
GPU-hours
samples seen
Why does the JiT-DDT work?
We think that it's useful to look at the JiT-DDT in the context of three papers (iREPA, Self-Flow, RAE v2), to try to unpack why our architecture works in the first place.
DiTs struggle to learn structure on their own
As we mentioned earlier, REPA has become a standard way to accelerate DiT convergence. The original authors tried a few different vision encoders and found that DINOv2 worked the best. But, it wasn't until iREPA late last year that anyone took a serious look into why DINO seems to work so well.
iREPA trained a bunch of generative image models on ImageNet with REPA, using a larger test bed of vision encoders. They looked at the models' gFID scores and tried to determine whether generation quality could be attributed to either the vision encoder's understanding of the holistic image or its understanding of spatial structure.
For holistic understanding, they relied on linear ImageNet probes. For spatial structure, they constructed a suite of self-similarity metrics. These quantify how much more correlated patches from an object are to each other than patches from other objects in the same image (e.g. patches of a lion's mane should be more correlated with other parts of the lion's mane than patches of the background skyline).
They found that higher ImageNet probe accuracy predicted worse gFID, while higher spatial self-similarity predicted much better gFID. Accordingly, it seems like REPA accelerates training by getting early layers of the network to see local structure, not holistic visual concepts.
Higher ImageNet accuracy, worse gFID; higher self-similarity, better gFID
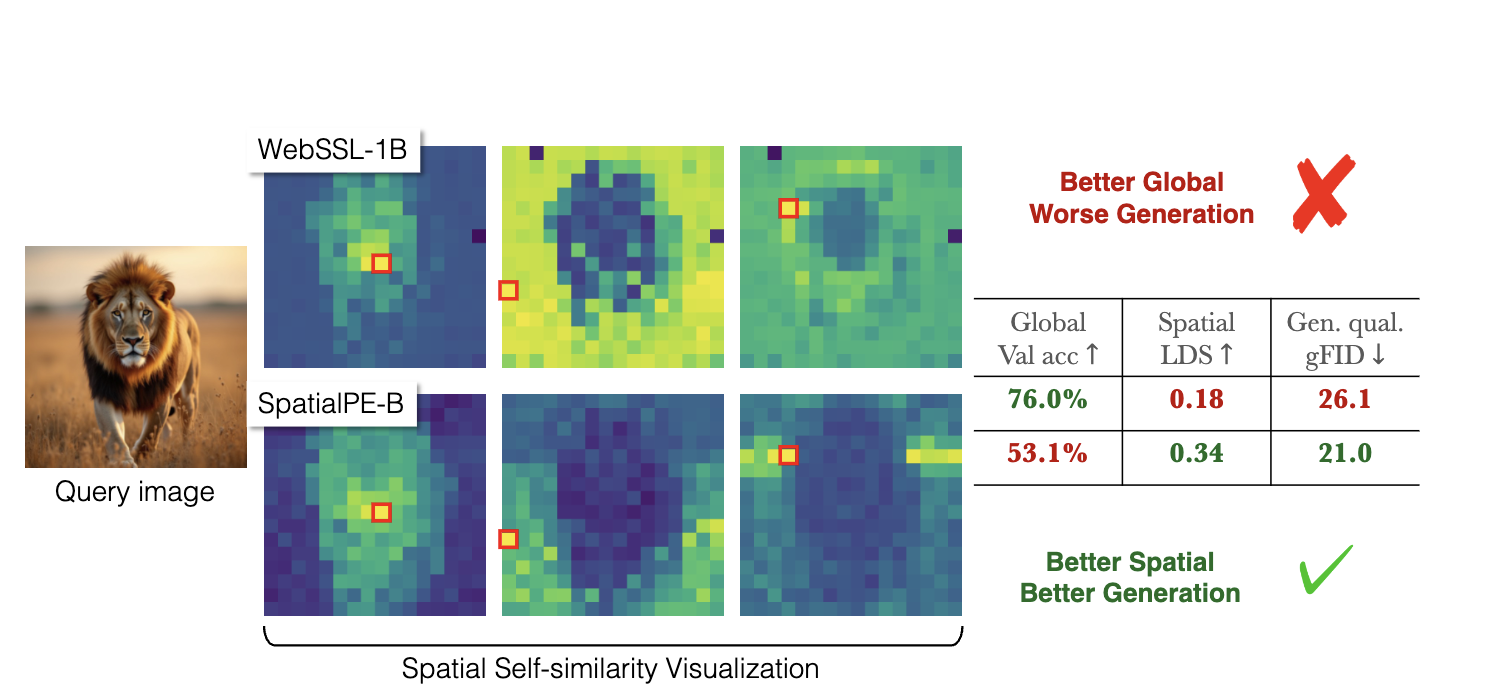
Here, we have two distinct vision encoders, WebSSL-1B and SpatialPE-B. WebSSL-1B scores higher on the ImageNet probe (76.0% vs. 53.1%) but lower on spatial self-similarity (0.18 vs. 0.34).
Pay attention to the red box in the middle column, highlighting the dead grass. Yellow is most correlated, green is somewhat correlated, and blue is least correlated. In WebSSL-1B, the grass is correlated with everything but the lion (e.g. correlated with the sky). Meanwhile in SpatialPE-B, it's only correlated with the other blades of grass.
The iREPA authors find that DiT aligned to WebSSL-1B generates worse images than those aligned to SpatialPE-B (gFID 26.1 vs. 21.0). Figure from iREPA (2025).
We think that this finding rhymes with the encoder-prediction task in our JiT-DDT. Downsampling images (e.g. 512×512 to 64×64) strips images of all detail, leaving us only with structure. By predicting the low-resolution image early in the JiT-DDT, we are providing a similar signal.
Learning structure earlier in the DiT unlocks better image generation
Taking a step back, it feels really weird that we're aligning a multibillion parameter DiT to the hidden space of a ~100M unsupervised vision encoder. Bigger models should have more capacity, so it's sus that we're relying so much on the representation space of a tiny model.
Black Forest Labs (the authors of Stable Diffusion and FLUX) seem to agree with our premise. In Self-Flow, they throw away DINO and achieve better FID results by aligning to the hidden states later in the network.
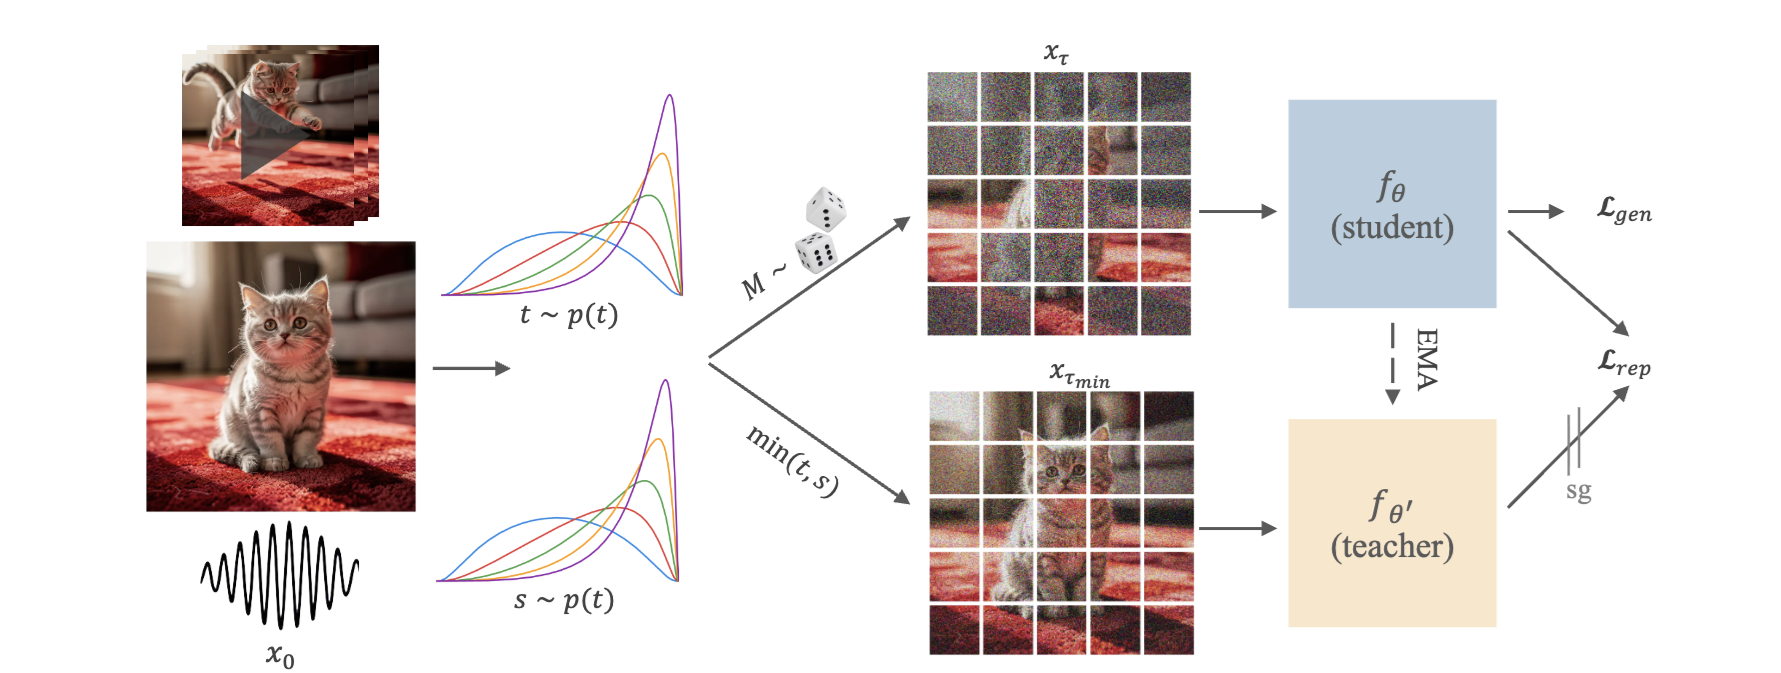
Another paper from last year found that the later layers of the DiT learn structure quite quickly, while early layers lag significantly. If the deeper layers already learn this structure without external intervention, we can simply align to them. This way you accelerate learning, without the representational ceiling imposed by traditional REPA.
We see Self-Flow and our JiT-DDT as cousins of sorts, tackling 3 core problems with different solutions:
- Slow Structure Learning in Early DiT Layers: Self-Flow aligns to later layers that have learned structure. We make structure learning explicit by regressing the low-resolution images with our encoder.
- REPA's Loss of High Frequency Details: We view Self-Flow as a form of self-distillation. It allows the model to make better use of its billions of parameters, freeing up later layers to generate detail once the early layers learn structure. We achieve the same effect by having two patchifications: one coarse and the other fine. The encoder learns structure explicitly, propagates its representation, and frees up the decoder to explicitly learn detail.
- Insufficient Exposure to Low-Noise Timesteps: Self-Flow relies on dual-timestep noising, which provides additional exposure to low-noise timesteps. We explicitly widen the noise distribution, after structure is learned.
Early on, we tried JiT + Self-Flow and it performed worse than JiT + PixelREPA.
Our gut is that this discrepancy just comes down to the amount of samples seen during the training. We use 100-150M samples per experiment. We can't tell from BFL's primary figure how many images they used in ImageNet training.
When we dropped PixelREPA from our JiT-DDT, the images were 5-10% worse. So, it looks like distillation from the auxiliary vision model remains helpful in low sample regimes.
Since we view JiT-DDT as a cousin of Self-Flow, we'd like to eventually train our architecture on 10x more samples with/without PixelREPA and see if we can get better generations without the auxiliary vision encoder.
One more thing to call out is that there is a clear discrepancy in the effect the REPA has in pixel space versus VAE latent space. Plain REPA actively hurt our JiT. That's why we switched to PixelREPA in the first place. We ablated whether to keep PixelREPA on for the entirety of training or switch it off midway (as is conventional wisdom). The results were a wash; PixelREPA's masking op might be a regularizer helping us avoid overfitting to DINO space.
Boosting gradients early in the DiT accelerates learning
While Self-Flow finds a path forward without DINO alignment, others have gone the other way. In RAE v2, the authors achieve SOTA on ImageNet FID by training a DiT in DINO space.
Instead of using patches like our pixel space models or VAEs like BFL, they run DINOv3 on all of their images, summing together the hidden states across many layers of DINO to come up with a representation. They then train two independent models, the flow matching generative model and a decoder from DINO space back to pixel space.
If you're training in DINO space already, it'd be logical to axe out REPA. But turns out, it still unlocks better generations in RAE v2. Let's pause for a second. That's really weird.
The authors find that REPA reduces to x-prediction within RAE v2, because the DiT's latent space and the alignment loss are both derived from DINO. Obviously, this rhymes with our JiT-DDT; we're also doing x-prediction early in our DiT via our encoder. But, we think this points at a deeper point — the DiT has a gradient propagation problem.
Self-Flow in latent space, RAE v2 in DINO space, and JiT-DDT in pixel space all improve model performance by introducing a loss term earlier in the network. It seems like all these models need additional gradient highways to learn more effectively. We're actively digging into this and will report back on this soon.
Appendix
Below are side-by-side comparisons of Linum v2 and JiT-DDT on 26 different prompts. All images generated by Linum v2 are 256×256 and all JiT-DDT images are 512×512. A few things stand out:
- The JiT-DDT is far more faithful to art styles than Linum v2. See [9 - charcoal drawing], [17 - Roman-style mosaic], [19 - oil painting].
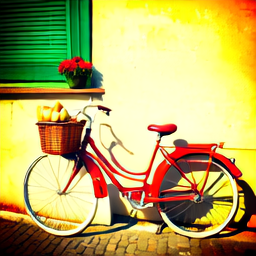
- The JiT-DDT generates images with far more realistic lighting than Linum v2. See [1 - three croissants], [20 - typewriter], [23 - red bicycle]. Linum v2 was far more liable to generate over-saturated images.
- The JiT-DDT still struggles to generate realistic human faces when they aren't the focus of the image. See [10 - chef's eyes closed], [14 - eyes scrunched up on woman's face], [24 - mouth, eyes malformed]. Training for longer, rebalancing the dataset to focus on these samples, DPO post-training, or scaling up the model itself should address these issues.
Linum v2
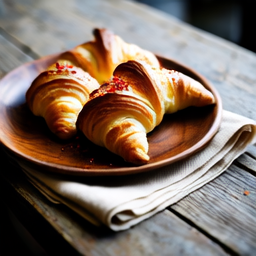
JiT-DDT
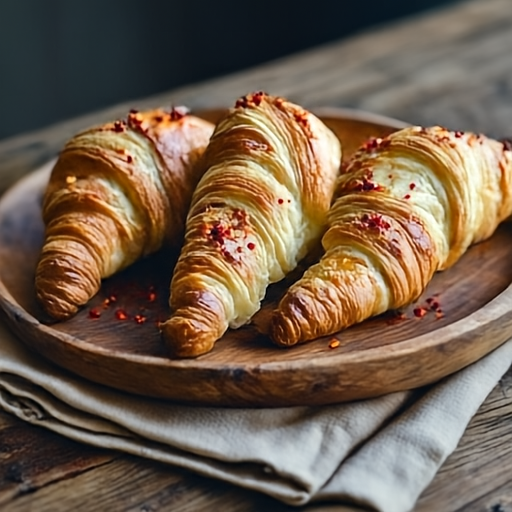
Three golden-brown croissants rest in a row on a rustic wooden plate, the plate itself sitting atop a folded beige cloth napkin on a weathered wooden table, viewed from a slight high angle. Each flaky crescent is dusted with a sprinkle of vibrant red pepper flakes. Natural side light rakes across the laminated layers to emphasize their crisp, buttery texture. A shallow depth of field softens the table edge and background.
Linum v2
JiT-DDT
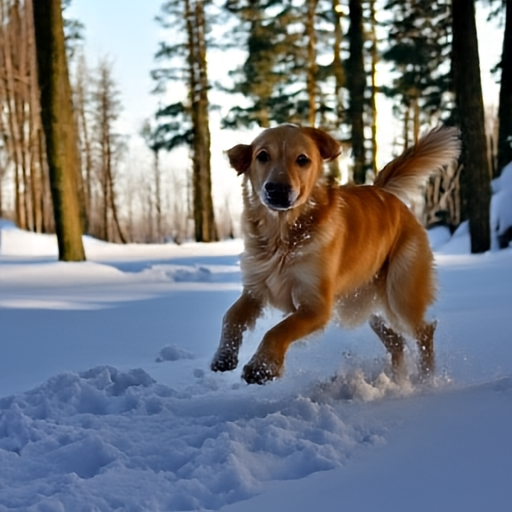
A golden retriever jumps out of fresh powder snow in a sunlit forest clearing, centered in the frame with its ears perked up. Fine snow dusts its paws and catches the low morning light. Tall evergreen and bare deciduous trees ring the clearing in the background, softened by a shallow depth of field. The crisp, high-key winter light leaves the brightest snow overexposed.
Linum v2
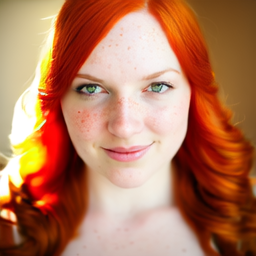
JiT-DDT
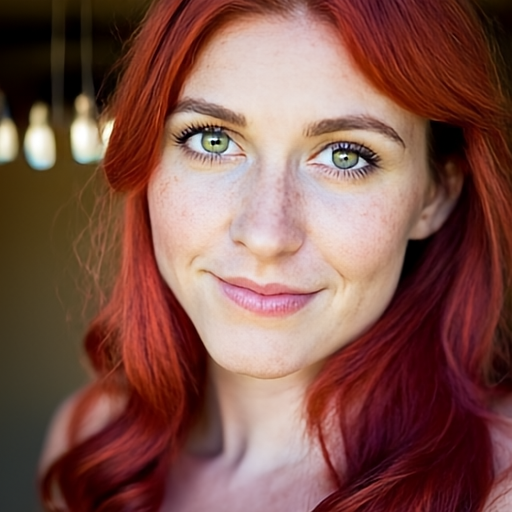
A close-up portrait of a young white woman with vibrant, fiery red hair cascading over her shoulders in soft waves, framed from the shoulders up and centered against a softly blurred warm-toned background. Her fair, lightly freckled complexion sets off piercing green eyes and a subtle, closed-lipped smile. Soft natural light enters from the left of the frame, highlighting the texture of her hair and the curve of her cheek while leaving the right side in gentle shadow. A shallow depth of field renders the background into smooth, neutral bokeh. Lights dangle out of focus on the left side of the frame.
Linum v2
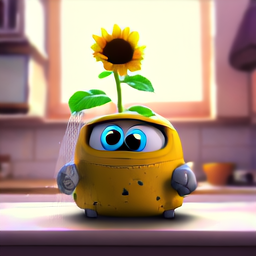
JiT-DDT
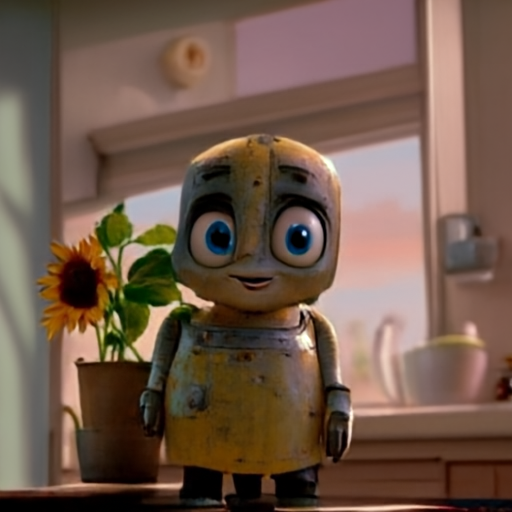
A 3D animated image of a small rounded robot with big expressive blue eyes standing near a potted sunflower on a windowsill, centered in the frame and rendered with soft subsurface lighting. Its dented metal body has a cheerful yellow paint job with scuffs. Warm morning light streams through the window behind it, casting a gentle glow on the leaves. The background kitchen is softly blurred
Linum v2
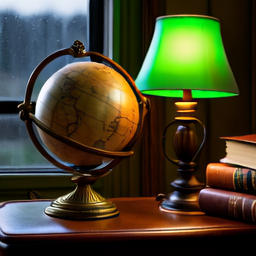
JiT-DDT
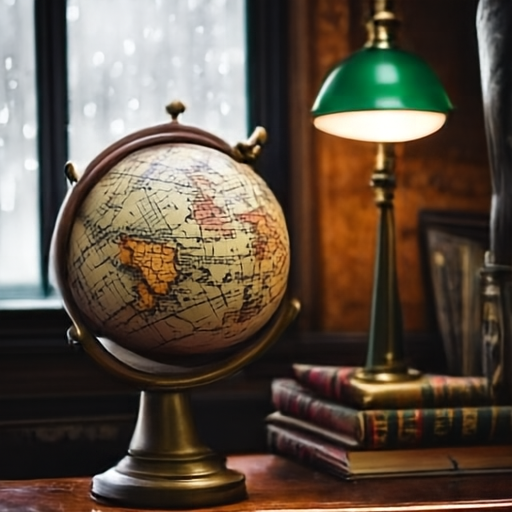
An antique wooden globe on a brass stand sits on a leather-topped desk in a dim study, positioned slightly left of center, its aged map showing faded oceans and hand-drawn continents. A green banker's lamp on the right casts warm light across the globe and a stack of leather-bound books. A window behind shows a rainy gray evening. The rich browns and greens give the scene a scholarly, quiet mood.
Linum v2
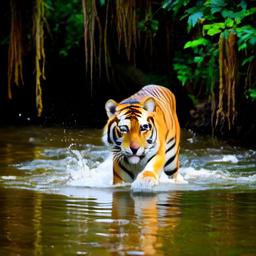
JiT-DDT
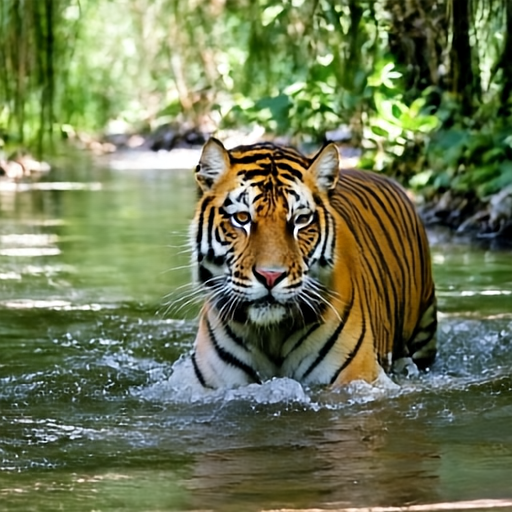
A Bengal tiger wades through a shallow jungle river, its orange and black striped body centered in the frame and water splashing around its chest as it moves toward the viewer. Dense green foliage and hanging vines line the riverbanks. Dappled sunlight through the canopy throws bright spots across the water and the tiger's wet fur. Its amber eyes are fixed directly ahead in sharp focus.
Linum v2
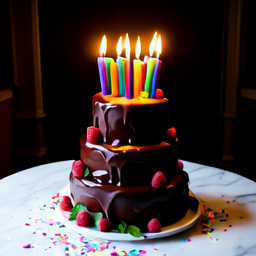
JiT-DDT
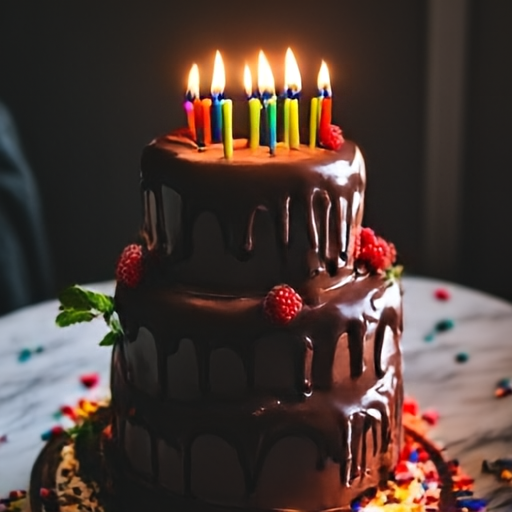
A three-tier chocolate birthday cake covered in glossy ganache and topped with a ring of lit rainbow candles sits centered on a white marble table in a dark room. The candle flames cast a warm, flickering glow across the cake and the scattered confetti below. Fresh raspberries and mint leaves decorate the edges. The background is nearly black, making the flames and dripping ganache the focal point.
Linum v2
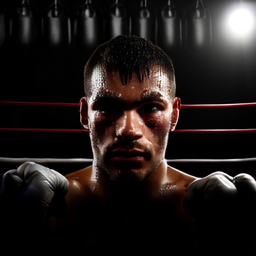
JiT-DDT
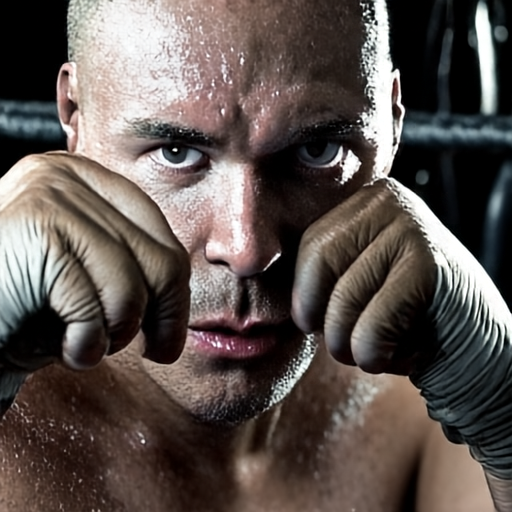
A close-up portrait of a sweat-drenched boxer with wrapped hands raised in a guard, framed from the shoulders up and centered against the dark ropes of a gym ring. A single hard light from the upper right carves sharp highlights along his brow and cheekbones and leaves the left side of his face in deep shadow. Beads of sweat catch the light. The background of hanging heavy bags is nearly black and completely out of focus.
Linum v2
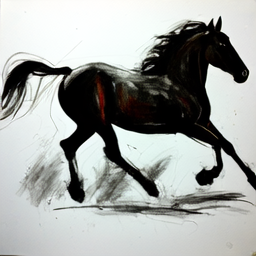
JiT-DDT
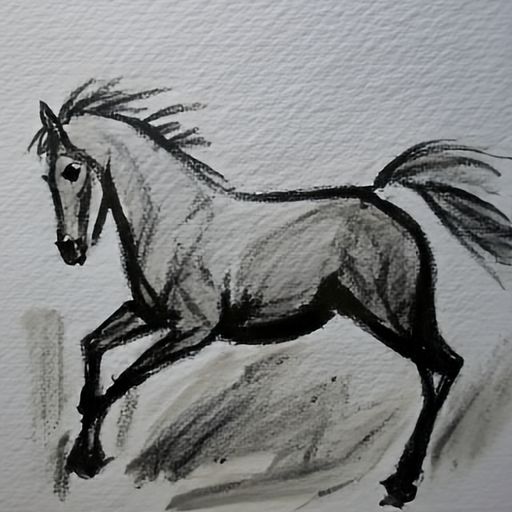
An expressive charcoal drawing of a galloping horse in profile moving from right to left, its mane and tail rendered in loose, energetic strokes on textured white paper. Heavy blacks define the body and legs while smudged gray tones suggest dust and motion around the hooves. The background is left mostly untouched with a few sweeping gestural marks. The drawing feels raw and immediate, with visible finger smudges.
Linum v2
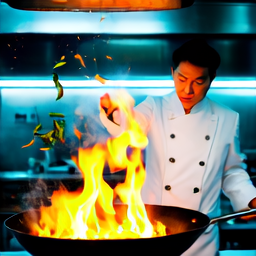
JiT-DDT
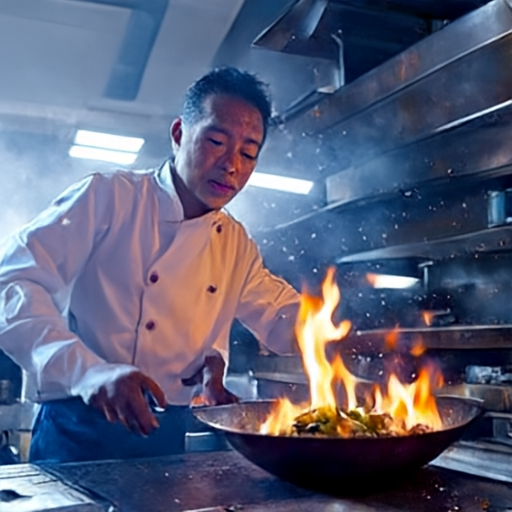
A middle-aged Asian chef in a white double-breasted jacket tosses vegetables in a flaming wok, positioned center-left in a busy stainless-steel restaurant kitchen. Orange flames leap from the pan and light his focused face from below, while cool blue fluorescent light fills the background. Steam and small sparks scatter across the frame. Shot at a slight low angle with a fast shutter that freezes the tumbling vegetables mid-air.
Linum v2
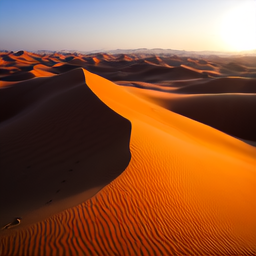
JiT-DDT
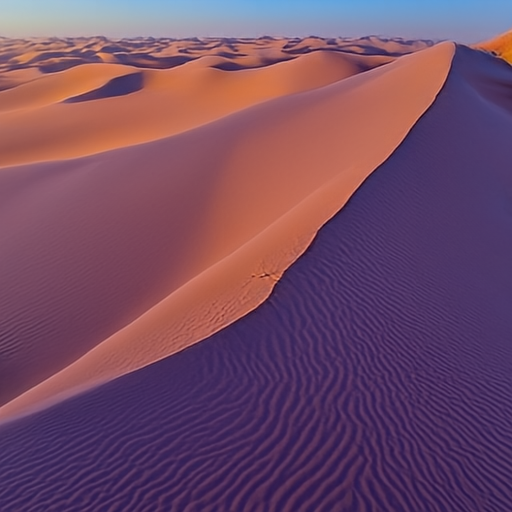
Sweeping orange sand dunes stretch to the horizon under a clear sky at sunrise, with a sharp crest running diagonally from the lower left to the upper right of the frame. Low sunlight from the right carves the dunes into bright ridges and deep purple shadows. Fine wind-blown ripples texture the sand in the foreground. A lone line of camel tracks curves over the nearest dune toward the distance.
Linum v2
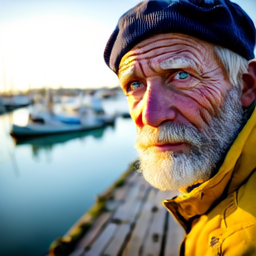
JiT-DDT
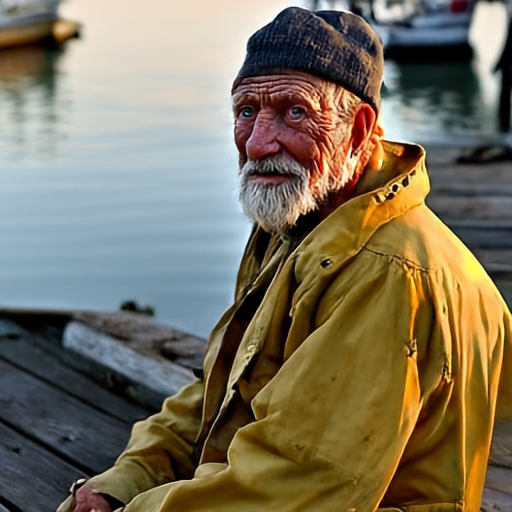
A weathered elderly fisherman with a white beard and deep sun-creased wrinkles sits on the edge of a wooden dock, framed from the chest up and slightly right of center. He wears a faded navy knit cap and a yellow oilskin jacket and looks off to the left with pale blue eyes. Golden late-afternoon light rakes across his face from the left, catching the texture of his skin and beard. A calm harbor with moored boats blurs softly into the background.
Linum v2
JiT-DDT
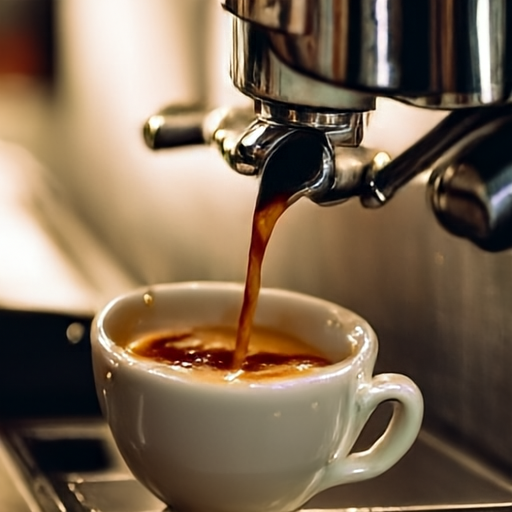
A close-up of dark espresso pouring from a chrome portafilter into a small white ceramic cup, centered in the frame, with a thick golden crema swirling on the surface. The stainless-steel espresso machine fills the background in soft focus. Warm cafe lighting from the upper left reflects in the chrome and the liquid stream. Small droplets are frozen mid-splash near the rim of the cup.
Linum v2
JiT-DDT
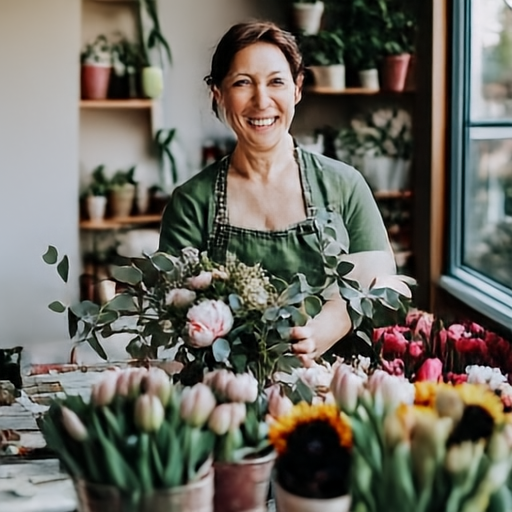
A smiling middle-aged woman in a green canvas apron arranges a bouquet of peonies and eucalyptus behind the counter of a small flower shop, framed from the waist up and centered. Buckets of tulips, roses, and sunflowers crowd the foreground in the lower third, and shelves of potted plants fill the background. Soft daylight from a storefront window on the right falls across her face and the pale pink petals. The depth of field is shallow, keeping her and the bouquet sharp.
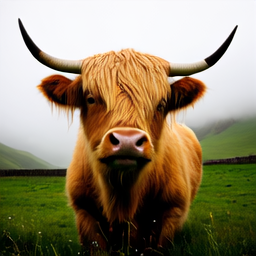
Linum v2
JiT-DDT
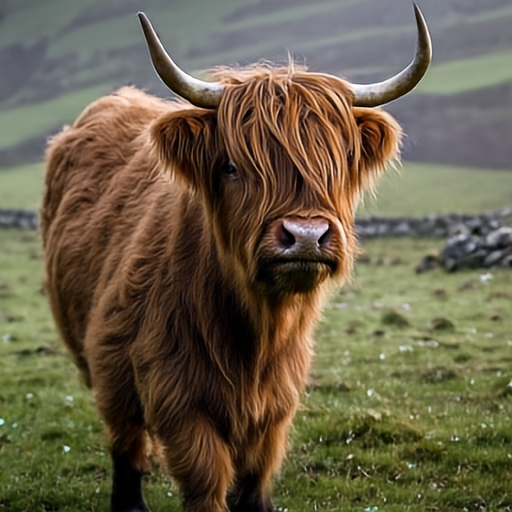
A shaggy Highland cow with long ginger hair covering its eyes and wide curved horns stands in a misty green Scottish field, framed from the chest up and centered, looking toward the viewer. Soft overcast light gives the fur a warm, tactile quality. Rolling hills and a low stone wall fade into fog behind it. Dew glistens on the grass in the foreground and the cow's wet nose catches a small highlight.
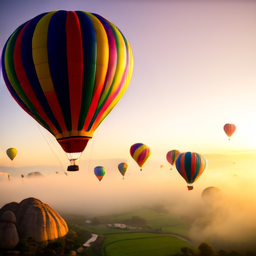
Linum v2
JiT-DDT
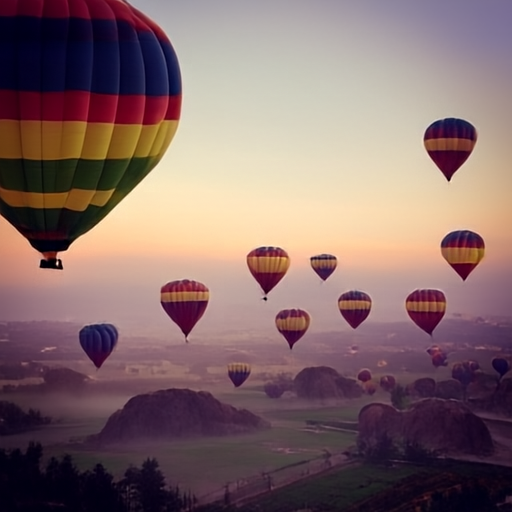
Dozens of colorful hot-air balloons in stripes of red, yellow, blue, and green drift over a misty valley at dawn, with the largest balloon filling the upper left of the frame and the others scattered toward the horizon. Low sunlight from the right rims the balloons in warm gold. Rounded rock formations and green fields sit below, partly hidden by mist. The sky is a pale wash of peach and lavender.
Linum v2
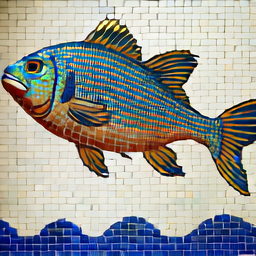
JiT-DDT
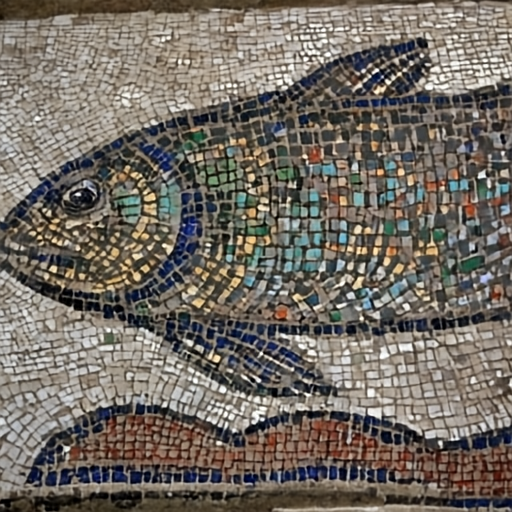
A Roman-style mosaic of a large fish swimming to the left, composed of thousands of small tesserae tiles in blues, greens, gold, and terracotta, filling the frame against a background of pale stone tiles. The fish's scales are picked out with alternating light and dark tiles, and a wavy band of blue tiles runs along the bottom. Grout lines and slight irregularities in the tile edges are visible. Even, diffuse light shows the surface texture.
Linum v2
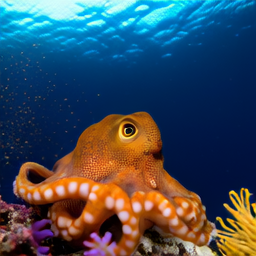
JiT-DDT
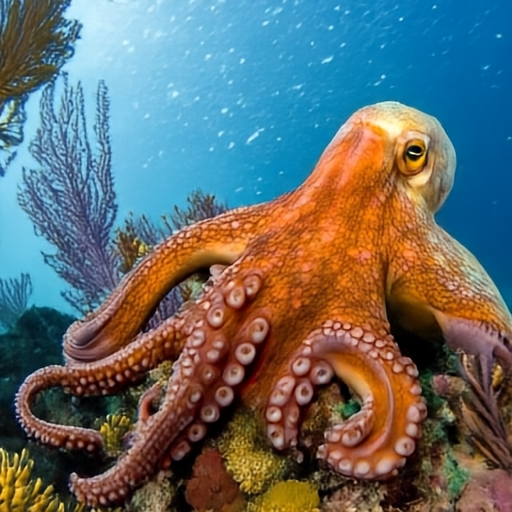
A close-up of a mottled orange octopus draped over a coral outcrop, its curling arms and suckers filling the lower half of the frame as it looks toward the viewer with a golden eye. Deep blue water and small drifting particles fill the background. Dappled sunlight from the surface above casts shifting light patterns across its textured skin. Small purple sea fans and yellow coral polyps frame the edges.
Linum v2
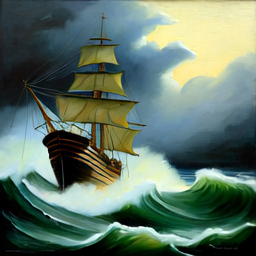
JiT-DDT
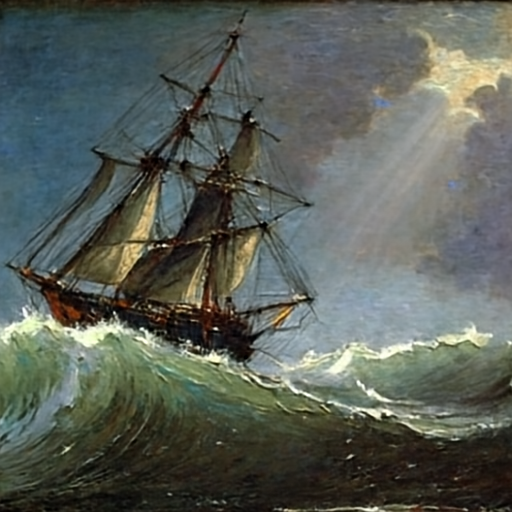
A dramatic oil painting in the style of nineteenth-century marine art depicting a three-masted sailing ship heeling in a violent storm, positioned center-left as enormous green-gray waves crest around it. Torn sails and rigging strain in the wind, and a break in the dark clouds on the upper right lets a shaft of pale light fall on the foam. Thick impasto brushstrokes render the spray and cloud. The palette is deep blues, grays, and bone whites.
Linum v2
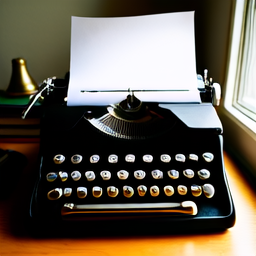
JiT-DDT
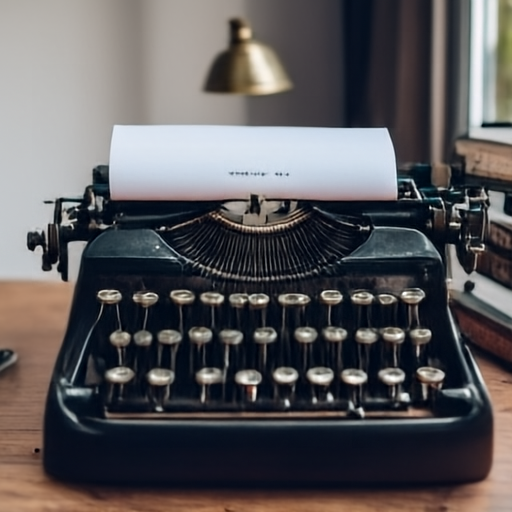
A black vintage typewriter with round chrome-rimmed keys sits on a wooden desk with a sheet of white paper rolled into its carriage, centered and photographed straight on from a slight high angle. A single line of typed text is visible on the page. Soft window light from the right highlights the keys and casts gentle shadows between them. A small brass lamp and a stack of books blur in the background.
Linum v2
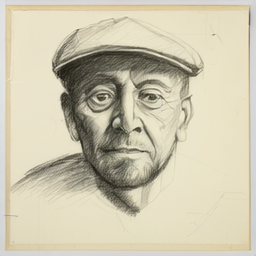
JiT-DDT
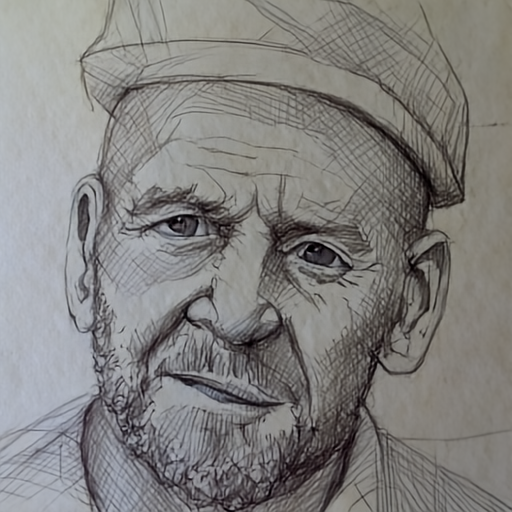
A detailed graphite pencil sketch of an old man's face in three-quarter view, framed from the shoulders up and centered on cream-colored paper. Fine cross-hatching builds up the deep wrinkles around his eyes and the texture of his short beard, while lighter strokes suggest a flat cap. The left side of the face is shaded in darker tones and the right fades into untouched paper. A few faint construction lines remain visible near the edges.
Linum v2
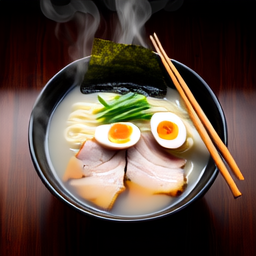
JiT-DDT
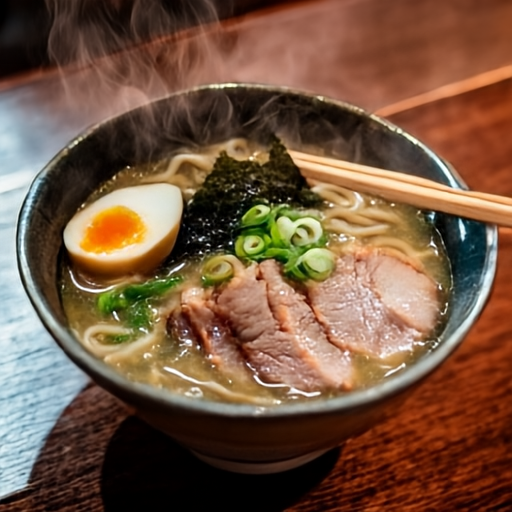
A steaming bowl of tonkotsu ramen sits centered on a dark wooden counter, viewed from a slight high angle, with slices of pork belly, a soft-boiled egg halved to show its orange yolk, green onions, and a sheet of nori arranged on top of the noodles. Wooden chopsticks rest across the rim on the right. Steam rises and catches a warm overhead light. The cloudy broth and glistening pork are rendered in sharp, appetizing detail.
Linum v2
JiT-DDT
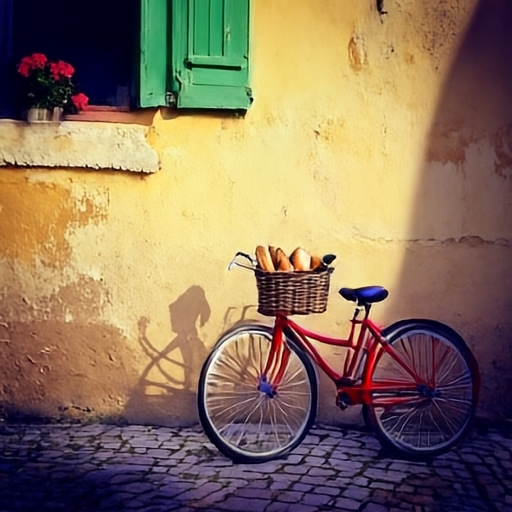
A vintage red bicycle with a wicker basket of fresh baguettes leans against a sun-bleached yellow plaster wall, positioned center-right in the frame. A green wooden window shutter and a small pot of red geraniums sit on the sill above the bike on the left. Bright afternoon sunlight from the right casts a crisp shadow of the bicycle across the wall and the cobblestones. The colors are warm and saturated.
Linum v2
JiT-DDT
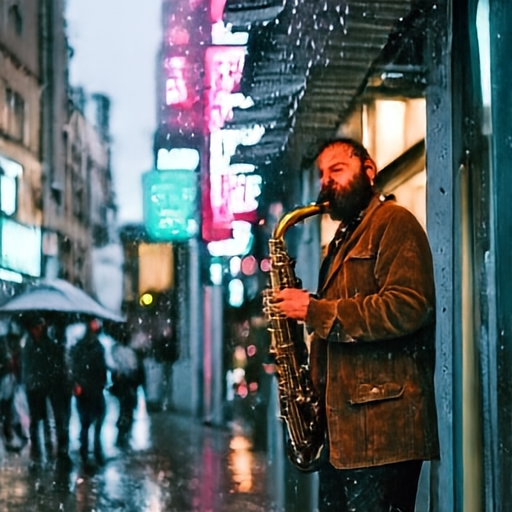
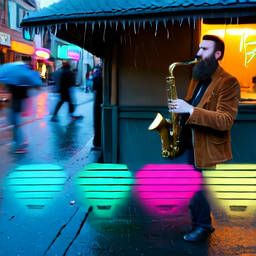
A bearded street musician in a brown corduroy jacket plays a saxophone beneath a dripping awning on a rainy city street at dusk, positioned right of center. Neon signs in pink and teal reflect in the wet pavement in the lower half of the frame, and blurred pedestrians with umbrellas pass on the left. Cool ambient light mixes with a warm glow from a shop window behind him. Raindrops streak across the foreground.
Linum v2
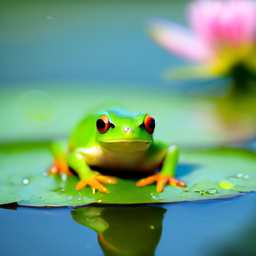
JiT-DDT
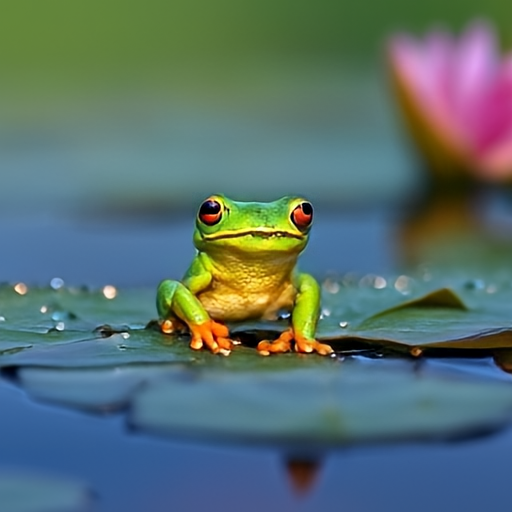
A macro photograph of a bright green tree frog with orange toes and red eyes perched on a floating lily pad, centered in the frame and viewed at water level. Dew drops bead on its glossy skin and the leaf's surface. Soft, diffused morning light gives an even glow, and the pond behind dissolves into a smooth green and blue bokeh. A single pink water lily blooms softly out of focus in the upper right.
Linum v2
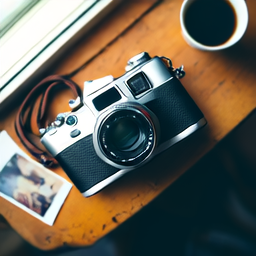
JiT-DDT
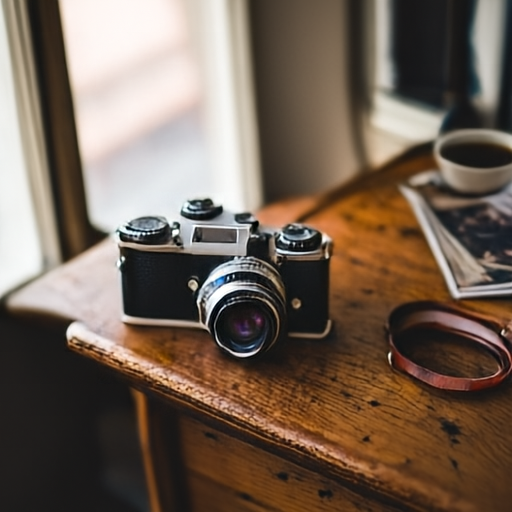
A vintage silver and black film camera rests on a scuffed oak desk beside a stack of faded photographs and a coiled leather strap, centered in the frame and viewed from a slight high angle. Warm afternoon light from a window on the left glints along the chrome dials and lens ring. A half-empty cup of black coffee sits out of focus in the upper right. The shallow depth of field keeps the lens crisp while the desk edge softens.
Authorship statement
We wrote all the words on this page. We used Claude Fable 5.1 to help us build the diagrams.
The Huggingface Model Card and Github Repo were written automatically by Claude Fable 5.1. We pointed Claude to our internal, experiment repo and had it pull out (and clean up) the necessary code.
Who are we?
We're two brothers training text-to-video models from scratch, trying to make animation accessible to everyone.

Get Field Notes
Technical deep dives on building generative video models from the ground up, plus updates on new releases from Linum.